Nixpkgs supply chain security project

Updates on the Nixpkgs security tracker

We’ve reached the Github login and manual record linkage milestone end of August. As of today, delivery of the project is late by another 4 months, after the last plan for being late by 8 months. It’s a disappointing result – many reasons, no excuses.

I’m back to it now and take budget responsibility and full accountability for getting the system into a state that is usable by the security team by Friday 2024-12-13. Which means that if you have questions, ask me directly. I allocated at least 5 hours per week on active planning and direction.

Ping me if you want to join the private Matrix room for beta testing, where we already collected some initial feedback from people involved in Nixpkgs security.

@erictapen will work full time on designing and building the user interface for the planned workflows. @raitobezarius will improve the performance of the data ingestion and processing pipeline, @proofconstruction will support us with backend-related tasks, both a couple of hours per week, with assistance from @alejandrosame as needed. @Erethon will latch onto the NixOS infrastructure team to ensure we have the service deployed to nixos.org for demo day.

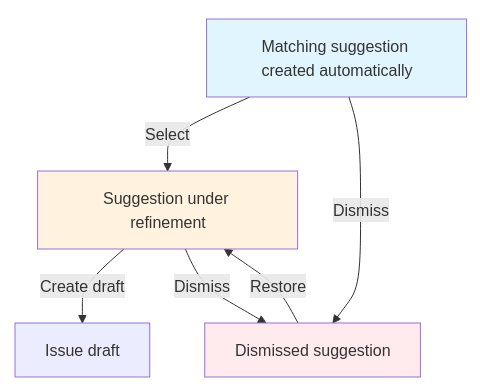
This week we have refined the user interactions to a degree where we can break down the implementation requirements into manageable chunks. The general idea is that a vulnerability record goes through three phases:

  1. Initial triaging

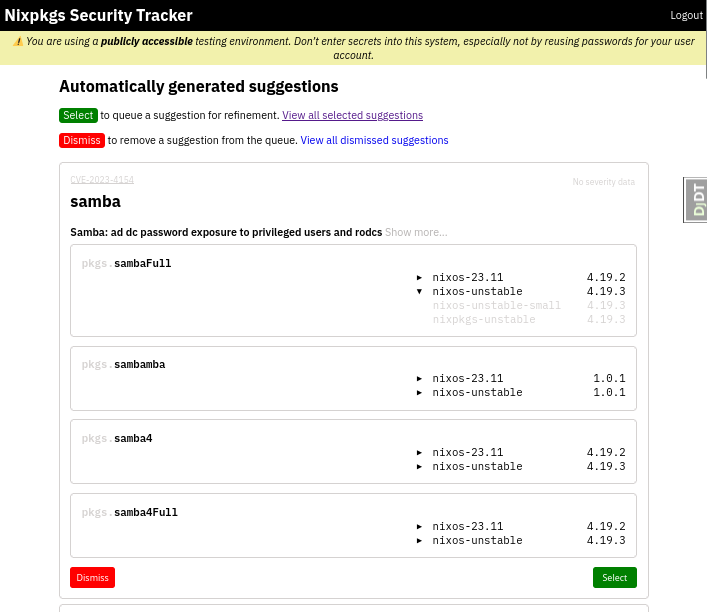
    Security team members get presented with a queue of pre-computed suggestions for matching CVEs to Nixpkgs derivations, which they would filter for things to inspect further. We already have most data to do a decent automatic matching, but it needs to be validated by humans, and we expect most of it to be thrown away. The aspirational goal is to make it convenient enough to ultimately reach “inbox zero”.

  2. Draft

    An automatic match will never be perfect, so a record needs to be adjusted. Many CVEs we get have duplicates, the contained information is often coarse or ambiguous, so the security team will have to check and possibly correct which derivations it applies to before publishing the record.

  3. Mitigation

    Once a draft is ready, it should be published as a GitHub issue where all affected maintainers are pinged. The usual workflow continues from there. Once the issue is closed, the vulnerability record is archived automatically.

You can follow progress in the milestones on GitHub.

We have a bunch of obvious refinements for these workflows in the backlog, such as smoother, structured searching and filtering for CVEs and derivations, and periodic notifications for security team members and maintainers, but those are currently not prioritised. We’ll focus on enabling the essential user stories for now.

On using GitHub dependency submissions

@sambacha Thanks for the pointer. I’ve investigated the possibility of offloading advisory handling to GitHub, and doing that can be at best considered future work.

There exist GitHub - tweag/genealogos: Genealogos, a Nix sbom generator · GitHub (@ErinvanderVeen) and GitHub - tweag/nixtract: A CLI tool to extract the graph of derivations from a Nix flake. · GitHub (@Arsleust) to generate dependency information that could be consumed by GitHub, but those can’t be used at Nixpkgs scale. The security tracker currently periodically evaluates all tracked channel branches and puts everything in a database. We could construct SBOMs or any required format from there and submit it within rate limits, but that’s essentially a different project altogether.

And then we’d still have an by far inferior UX to address advisories which, most importantly, doesn’t take into account how Nixpkgs is currently developed. This project is to serve the security team and package maintainers, and GitHub simply doesn’t support our current needs.

Last but not least, there are good reasons to keep our dependency to GitHub limited. Both STF and NGI are interested in us (and everyone else) adopting free and open source software for all workflows. Control over the supply chain is part of supply chain security.
16 Likes

We’re making progress. In the past six weeks we were fighting reproducibility issues, sickness, and various time sinks inside and outside of the project. @proofconstruction had to drop out, @erictapen iterated over a couple of designs, @raitobezarius supplied the data models and a staging deployment, @erethon made the first steps towards a deployment to official infra (thanks @Mic92 and the infra team!).

Two weeks ago we sent our beta testers an interactive demo for clicking around. Now the workflow for dealing with automatic suggestions to match CVEs with Nixpkgs derivations is morally complete, and we all have a much clearer vision of the look and feel we’re moving towards.

The main idea for the triaging is that the queue of automatic suggestions shrinks monotonically. Either a match is irrelevant, or it could be considered in more detail. If a suggestion is selected as a candidate, after removing irrelevant (and later maybe adding missing) affected derivations, it’s supposed to be moved to the next step in the process: a draft security issue, where one can adjust more details and eventually notify maintainers.

Note that we’re currently focused on defining workflows and visually structuring the available information. Fine-tuning colors, shapes, and proportions will happen later in the process.

image

We didn’t fully complete our objectives for the first milestone due to some unexpected delays and tricky details that needed to be figured out. What was originally intended to be “quick triaging” was cut down in scope and renamed to basic triaging. We still have to make accessible more data to show for at-a-glance decisions, the query performance is not suitable for real-world use yet, and there’s still a bug in the record linkage algorithm that creates countless duplicates.

The next steps will therefore revolve around making the triage workflow more practical – primarily by reducing the amount of noise and uncertainty – with things such as:

  • showing derivation descriptions in the overview
  • allowing removal of unwanted derivations
  • filtering out dependent derivations
  • sorting suggestions by relevance
  • fixing various bugs and problems with the data
  • displaying state changes in an activity log

@alejandrosame will join us to finish some backend work left over from summer. The plan is to reach the second milestone end of next week or beginning of the week after next, with the goal to have a triaging workflow that feels about right, even if it’s still slow. We’ll then continue with implementing “editing a draft security issue”.

Given all the complications so far, it’s likely we won’t get to “publishing issues” by mid December. It seems there’s still a lot to do for just making the thing run continuously. The development setup is finicky. It’s a lot of data, and many moving parts on the way to presenting it. Ensuring minimal stability always took the largest part of the time, already since the beginning more than a year ago. This is why the user-facing features still appear rather basic so far.

But overall this is finally coming together! By skimming through the data we already found some vulnerable packages. And it promises to become quite satisfying to discover even more, so I hope that more people will pick it up once it’s deployed in production. Even with some comfortable automation lacking, I’m convinced the insights the security tracker will provide to the security team and maintainers will make a big difference for making Nixpkgs and NixOS a reality day to day.

14 Likes

I wonder if folks working on this project evaluated GitHub - tiiuae/sbomnix: A suite of utilities to help with software supply chain challenges on nix targets and determined whether the work there might be useful in this project?

2 Likes

Yes, we did. @raboof even contributed code. That type of local scanner solves a different problem: which packages do I have on my system that may be affected by vulnerabilities? The online security tracker is for distribution maintainers and helps answering: Which vulnerable packages do we have in our distribution channels? The first is useless without the second, because you can’t upgrade if there’s nothing to upgrade to. Maintainers need to know which fixes to apply and which mitigations to prioritise so users have a chance to run secure systems.

Local scanners also deal with different internal problems, mainly an abundance of false-positive matches. The system design for the development program here envisioned improving upon that as well, by providing more accurate data based on the upstream triaging.

6 Likes

I hear you.

Just for whatever it’s worth, In some contexts, I was using sbomnix to scan packages for known vulnerabilities on package sets that I would then distribute to many users. Although it is then some work to map those found vulns to an upgrade path in new releases, or a published patch. There could be false positives, and it did take some tuning, but after some effort I did not experience an abundance of false positives.

But in any case, thanks for answering that, and it seems reasonable to me that this wasn’t a good fit for the use case of nixpkgs supply chain security now that I understand more.

3 Likes

We’ve come a long way since the last update, and are looking forward to our demo day this Friday 2024-12-13T12:00:00Z with the NixOS security team and anyone interested to participate (send me a message to get a calendar invitation).

Triaging is now indeed quick thanks to a number of optimisations, and @erictapen has taken great care to provide as much relevant information as possible at a glance while not overloading the user interface with noise. Last week we closed the second milestone.

At the time of writing, we’ve implemented 17 user stories (distinct workflows or behaviors) and addressed 30 other issues. The system is visibly taking shape.

We’ll spend the next days on smoothing down the most obvious rough edges and doing minor cleanups[1], expecting to finish 6-9 more user stories.

This will leave us with ca. 30 user stories and more than 50 other issues “discovered” on the way, which better be addressed before committing to a production deployment. While there’s always more work to do, it seems like we have now done the hardest, first 30% of it. This was made possible thanks to the investment by the Sovereign Tech Fund, detailed in the top post. After a successful presentation, we hope to obtain the means to get through the next 30-50% in 2025.

Ping me if you want to join the private Matrix room for beta testing or participate the demo.


  1. Cleanups such as fixing a typo in the CSS class name that messed up the highlighted hint in the screenshot after a renaming. These things simply require playing around with the application while paying attention to details. ↩︎

14 Likes

Thanks for the demo! It was really helpful to see everything in action and I’m looking forward to where this project ia going. Thanks you all also for all the hard work in implementing this! :pray:t2:

2 Likes

Hello all,

Again, thanks for the demo the other day. It took me more time than I expected initially but I played with the security tracker and collected my thoughts/feedback on what I feel it is missing or would be needed at some point. In any case clearing the remaining technical roadblocks so we can publish issues should take priority, it will be easier to determine what is needed/most useful if we can exercise the whole workflow.

First of all, I want to say that the security tracker has already proved useful in its current state. I spotted vulnerable packages that I would otherwise have missed. The workflow with the suggestions is quite efficient. Thank you all for your work :blue_heart:

In no specific order, grouped using the same personas as the ones described in the README.

As a security team member / triager:

  • it would be nice to have the ability to remove a release branch from an issue, sometimes older versions are not impacted by a recent vulnerability but the CVE metadata are not always good enough to determine that (or a feature was not enabled in older nixpkgs release branch)

  • having the possibility to add some notes on an issue would also be nice, it is not always obvious why something can be dismissed or where to find the fixes

  • the suggestions are sometimes a bit noisy, when I tested wordpress things were one of the worst offenders and I saw you already spotted similar issues and attempted some approaches in Improve matching suggestsions quality · Issue #391 · Nix-Security-WG/nix-security-tracker · GitHub I’m not sure if there is a better way to achieve that :confused:

  • sorting the suggestions in a different order could help to prioritize the work, I’m thinking of something like “Vulnerability affecting packages of a special set that should get priority handling (e.g. browsers)” → “Vulnerability affecting packages with a rebuild count > 500 (that should make vulnerabilities affecting packages like gstreamer more visible)” → everything from newest to oldest

  • we might need some intermediate stages between “draft” and “published” to handle situations where a vulnerability is confirmed but a fix is not yet available or to distinguish issues where the remediation work has started in nixpkgs from the ones where nothing has been done yet

  • we might need to create issues without having a CVE ID because it has not yet been assigned/published or because none was requested

  • should we consider vulnerabilities caused by specific nixpkgs/NixOS implementation and not by the packages themselves?

As a nixpkgs user:

As a nixpkgs maintainer:

  • A quick access from the issue page to the related issues/PRs per affected release branch

  • The ability to filter issues affecting packages that I maintain

6 Likes

Thanks a lot @tgerbet for the feedback, this is really valuable!

The idea is – at least for the next implementation phase – for “published” to mean that there’s a GitHub issue published to which all related issues and PRs can refer. Once that issue is closed, the tracker issue gets closed as well. We wanted to populate the issue description with all the data we have and also ping maintainers as set in the draft.

All the other items you mentioned are also on our radar, and it’s great you mentioned them explicitly since that will inform prioritisation.

3 Likes

Work on the Nixpkgs security tracker continues: In the next couple of months, @yannham @florentc from Tweag will implement publishing and configuring notifications for package maintainers and Nixpkgs users. The goal is to get the system closer to continuously running in production. @erethon will support us by making the deployment more robust and self-contained. See the notifications milestone for details on the scope, and the project board for more information on current progress.

Early feedback welcome! I’ll post updates here when there’s something notable to play around with.

This is part of a larger effort on improving supply chain security in Nixpkgs, which also involves activities by @infinisil @YorikSar @balsoft.

17 Likes

Some updates:

19 Likes

Has there been discussion of also adding CVE status to package metadata as well? With just the CPE, we still have to track the status and resolution of CVEs in an external tool or database. Tools like sbomnix will add patches to the Cyclone DX pedigree but there’s still no complete, Nix-friendly tool for tracking CVE status (affected, not_applicable, resolved).

Often many CVEs must be marked as not_applicable due to the NVD and other databases being very noisy and containing incorrect data. It would be very convenient, to track CVE status centrally in nixpkgs. When packages are updated or patched to fix a CVE, the CVE can be marked as resolved in the same commit.

We currently have meta.knownVulnerabilities but this only tracks true-positive CVEs. Currently the CVE is simply removed once resolved which is problematic since many CVE scanner tools will produce false-positives because the NVD database often has incorrect version info, incorrect CPE metadata, etc. If we kept coherent status of CVEs, we could update tools like sbomnix,vulnix, etc. to use this metadata to produce more correct reports.

Yes, there’s this reference to an early issue from the vulnerability tracker (not much to see there though, the discussion was mostly verbal).

@raitobezarius’ design idea for the tracker is to be that central place, with a much more ergonomic UI and easier to deal with API than manipulating source code. The linked issue tracks the aspect of feeding back status information into the source. But it’s very low priority right now, as there are lots of immediate practical challenges to resolve before it becomes relevant, and querying the tracker can be made workable much more easily than talking with the source, as @raboof’s prototype (which calls sbomnix under the hood) demonstrates: GitHub - Nix-Security-WG/nix-local-security-scanner: Reports on which security advisories may be relevant for a given system or derivation Also, as opposed to exclusively relying on GitHub or the Nixpkgs contribution process, the tracker can be self-deployed, and we’ve been working on making that easier in the past weeks.

2 Likes

Hi everyone! It’s been a year again and we’ve gotten a lot done, with great many thanks to a client of Tweag funding continued development.

Most importantly, the Nixpkgs security tracker (which we have established as its proper name) has run productively since the last update. Due to the tireless effort of the NixOS security team it already has opened 2200 GitHub issues notifying package maintainers of vulnerabilities, 75% of which are currently closed. Hats off for @tgerbet and @hexa, who triaged thousands of automatically generated matches between CVEs and Nixpkgs derivations, and took the time to regularly meet with us and provide feedback on how to improve the tracker to better support their workflows!

Today we’re counting 13 000 processed CVEs, 55% of which were affecting Nixpkgs at some point, and 200 registered users.

Our contributions were mainly around keeping the thing operational and continuously making it more useful. That turned out surprisingly tricky! We have deeply nested data, a rather large amount of it coming in ever day, and hold up the ambition to never delete anything users have touched so it’s auditable for the foreseeable future. We also shoveled away at tech debt accumulated in the prototype phase, including figuring out a more sensible application data model and a strategy for incrementally migrating towards that.

Highlights of things done

@florentc is dealing with user-facing feature development, from early discussions and design to full-stack implementation:

  • Implemented a system subscribing to notifications on packages (including opt-out automatic subscription for registered maintainers) that also sends out emails

  • Built a togglable collapsed list view for a quick overview, and other ways to reduce the visual noise, such as buttons for ignoring irrelevant CVE references

  • Reworked the activity log backend, adding event debouncing and folding

  • Did a major refactoring of the prototype-phase UI code, making it much more robust and easier to reason about

  • Enabled structured dismissal reasons and free-form comments for quicker triaging and to serve as a basis for improving matching quality

  • Added a per-package view of vulnerabilities

    Clicking on a package attribute in a suggestion will show the list of CVEs matching that package and some filter controls as well as the link to the feed.

  • Added public Atom feeds, accessible through the per-package view

  • Designed a workflow for bundling matches into issues, to reduce the noise for maintainers who would otherwise get pinged for every CVE separately

    Many software projects release CVEs in batches, while maintainers would only need to update the version once to the one that has them all fixed.

  • Currently working on rebuilding the mostly static UI with a typescript framework

    That will make interactions much quicker and have fewer interruptions for users, and ease developing new features for us. The prototye UI had been made deliberately simple to get something off the ground, and now has outlived its usefulness.

Our new team member @adekoder is taking care of the database:

  • Implemented garbage collection on stale data, which slowed storage space growth to sustainable levels

    There’s currently work in progress to get rid of another large chunk of effectively unused data, and numerous less-low-hanging fruit in the pipeline.

  • Designed a method to cluster derivations into “packages”, giving us the most precise notion of which software Nixpkgs actually contains I’m aware of in the ecosystem

    It’s not yet accessible at the surface, but will soon allow us to handle attribute set aliases as one object, and thus further reduce the noise when triaging vulnerabilities. Since the number of packages is a lot smaller than the number of derivations, it will also reduce the server load.

  • Performed multiple complex asynchronous migrations to reduce storage requirements, query performance, and code clarity

  • Will soon deploy a mechanism to update untriaged matches to the latest evaluation, which will substantially reduce the backlog for the security team.

@erethon keeps the lights on at the infrastructure level:

  • Got everything ready for the live deployment
  • Set up metrics dashboards and alerts
  • Regularly helps me to debug all sorts of production issues, which keep coming with ever new surprises

@DarshanCode2005 is laying the ground for systematic improvements to the matching algorithm as part of his Google Summer of Code 2026 project by setting up the relevant metrics, and also keeps making thoughtful changes to the little things.

And I’m spending most of my time on support tasks:

  • Collecting requirements, communicating with stakeholders, and tending to the project board
  • Maintaining the build setup and development environment
  • Increased test coverage from almost nothing to almost complete
  • Continuously improving onboarding and contributor documentation
  • Tending to occasional volunteer contributions (thank you, everyone who submitted PRs, also for your patience!) and introducing new people to the project
  • Lots and lots of code reviews and design discussions

Next steps

That said, this service is still primarily an internal tool for the security team and package maintainers to streamline their routine communication concerning the Nixpkgs master branch. It isn’t very useful to package consumers yet: for example it doesn’t indicate whether a vulnerability is already fixed or whether a given commit is affected. Also you can’t search for packages or CVEs yet. We intend tackling all that once we have consolidated the current stream of work. The litmus test for that is being able to deal with Linux CVEs without hacks or heuristics.

One of the milestones on the way there is an API for power users who don’t want to wait for us to figure out the consumer workflows. @florentc already laid the groundwork with a token management system, OpenAPI spec generation, and rate limits, and keeps exposing more endpoints as we go.

Right now we’re primarily focusing on sustainability. People come and go, and the system should avoid burdening volunteers at all costs.

Long-term we want make more ambitious changes:

If you’re interested in following along with development, ask questions, discuss your use case, or help out in any capacity, please join the Nixpkgs security tracker Matrix room!

And if you want to get your hands on the code, it may be worth taking a stab at one of the many FIXMEs. We’re sprinkling them over the code for whenever somebody gets around to make some dusty corner nicer. Check the contribution guide to get started.

30 Likes